 NextFluent
How we count
The rules behind every figure.
A researcher should be able to defend any number in a meeting. These are the rules the desk follows, written down so you can. They are the same in the free sample on this site and on the desk.
Binding a question to a field
When a study is added, every question in the file is read once. The desk notes its wording, the words it also answers to, its grain (a parent question or one item of it), its tense (past, present, hypothetical) and its polarity (asked the positive way or the negative way). Those notes score every English question you type afterwards.
A question you ask is matched against every field and the fields are ranked. The top field is used only when its score clears a floor and it leads the runner-up by a clear margin. A question about last season is scored against the tense of each field, so it does not land on next season’s look-alike.
A pin is your decision, remembered. When you pin a wording to a field, every later ask with that wording goes to that field, and the card says it was pinned.
Every word settled
Finding the nearest question is not enough. A question can come nearest to one survey question and still carry a word from another: “how concerned are riders about the guided first ride” is nearest to “How valuable was the guided first ride?”, and “concerned” belongs to a different question. So before anything is counted, every word of your question has to be settled, one of three ways.
- By the question. The word is in its wording, in its answers, or in words you taught it.
- By the dictionary. The word shares a meaning with one of the question’s own: “closest” for “nearest”, “hold” for “have”. The dictionary is a fixed list of English words that ships with Fieldlock. It is a file, not a model: the same two words give the same result every time, and nothing you type is sent anywhere to look a word up.
- By a person, once. Anything else stops. The desk names the word, shows the questions it could mean and asks you to choose. Your choice is kept for that wording, on the desk and on your client’s page.
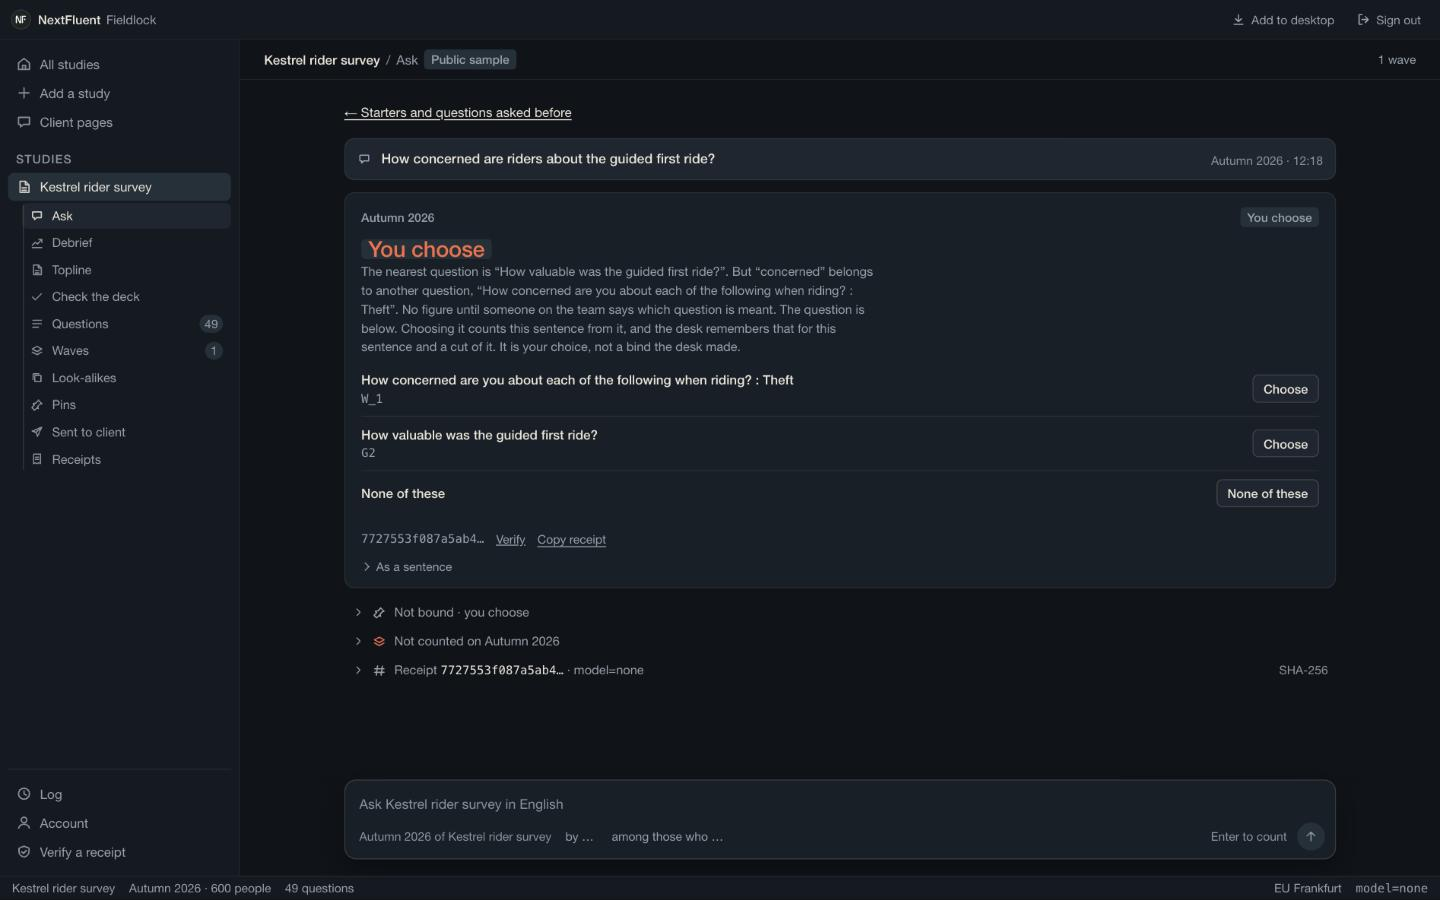
Some words are never taken as wording, whatever the dictionary says: a group the survey did not ask or did not split out (“plumbers”, “left-handed riders”), a time or a place it did not ask about (“in 2019”, “in Belgium”), a second question tacked on, a comparison, and an action with nothing after it where more than one question is about that action (“considering changing” what?).
How strict, study by study
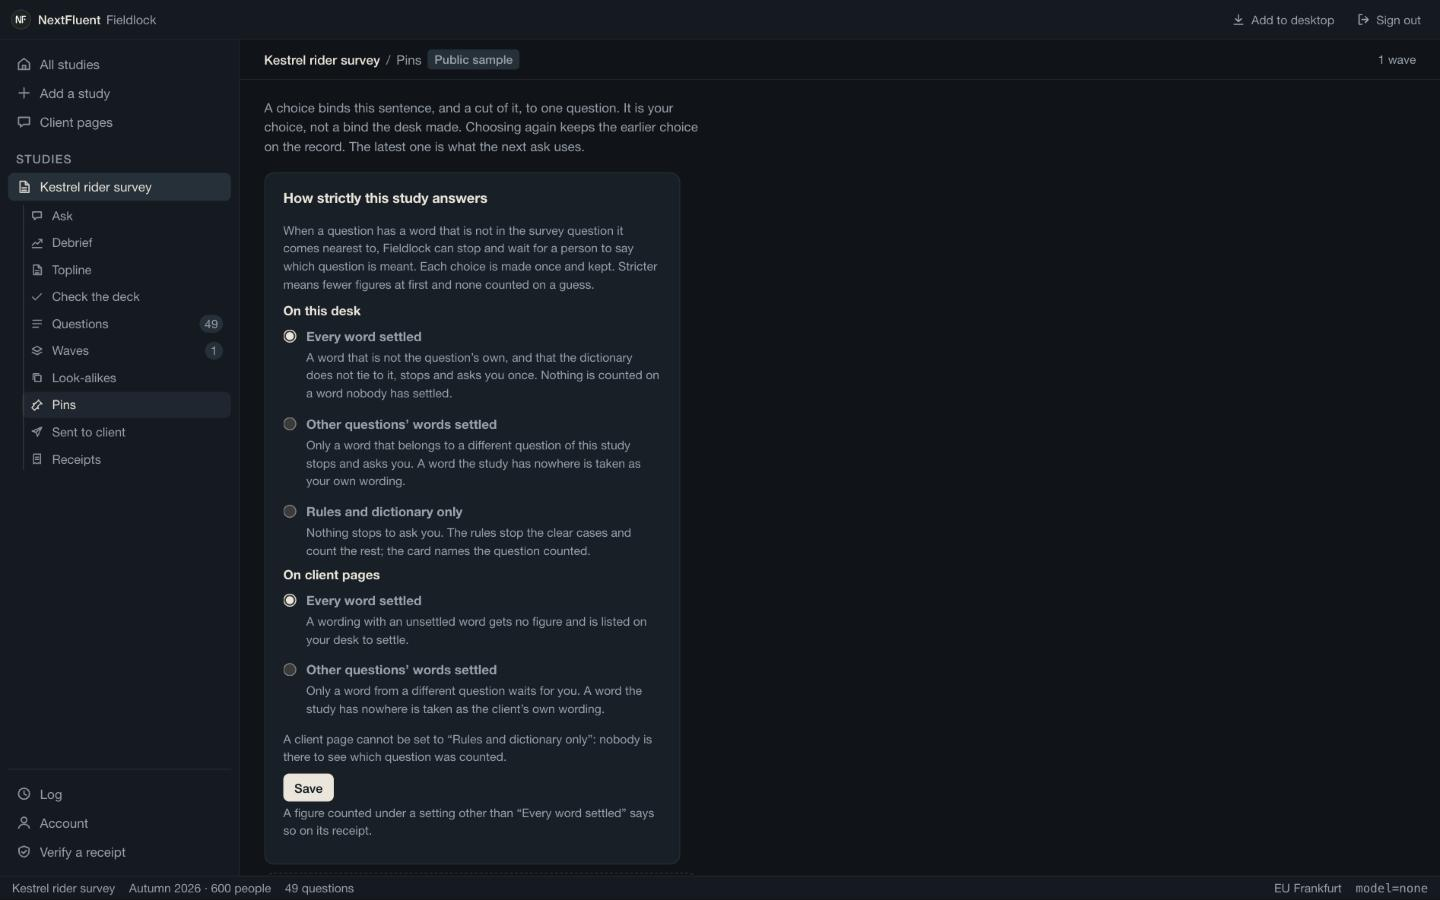
Each study has a setting, once for your desk and once for client pages. It starts at the strictest.
| Setting | What waits for a person | Where |
|---|---|---|
| Every word settled | Any word the question and the dictionary do not settle. | Desk and client pages. The setting every study starts on. |
| Other questions’ words settled | Only a word that belongs to a different question of the study. A word the study has nowhere is taken as your own wording. | Desk and client pages. |
| Rules and dictionary only | Nothing. The rules stop the clear cases and count the rest; the card names the question counted. | Desk only. A client page cannot be set to it: nobody is there to see which question was counted. |
A figure counted under anything but the strictest setting says so on its receipt. A change of setting is written to your desk’s log.
A small study, under forty questions, is held to every word with nobody asked: there is too little of it for a stray word to be anything but another question. That is how the Harborline sample on this site answers.
When there is no figure
- The question names something the study never asked about. The card says what was not found, and gives no figure.
- No field clears the floor. A nearest column is not used.
- Two fields score too close together. The card shows both and asks you to pin one. Your client sees “too close to call” and is told to ask you.
- A word in the question is not settled. The desk asks you once which question is meant. Your client’s page says the wording is not settled yet and that you have it, and the question is listed on your desk. Every word settled.
- The question asks about a group, a time or a place the survey did not, or asks two things at once. The card says which, and gives no figure.
- The field exists in the study but has no column on this wave. The card stays blank on that wave and names the look-alike that is in the file, with the percentage it would have given.
- A narrowed base falls under five people.
A refusal is a result. It gets a receipt and it can be sent to the client page as a blank.
The base
A percentage is counted on the people who answered that
question. Blanks are not in the base. The card shows the base as
n = 100 and the sentence says “of 100”.
“Among those who …” narrows the base to the people who gave one answer to another question. The card says who, and how many. A base under five people is refused rather than shown.
Weights and effective bases
A weight column in the file is applied and named. The weighted figure leads and the unweighted figure stands beside it, so nobody has to ask which one they are looking at.
Alongside the weighted figure the desk shows the effective base: the sum of the weights squared, divided by the sum of the squared weights. That is the base the significance tests run on when a weight is in play, so a heavily weighted cell is not treated as if it had more people than it does.
Cuts, column letters and the 95% test
Add “by region” and the figure is counted in each column of that question. Every column gets a letter. A cell lists the letters of the columns it is higher than at the 95% level, the way research tables have always carried them.
- Shares are tested with a two-proportion z. Means are tested with a Welch z on their spreads.
- Weighted figures are tested on their effective bases when every column has one; otherwise on unweighted bases. The footnote under the table says which.
- A column under five people shows “Too few people” instead of a figure, and no test is run on it.
Scales
A 1–5 agreement question or a 0–10 likelihood question is read as a scale. The desk works out which end is favourable from the answer labels. The card reports the favourable box, top 2 on a five-point scale and top 3 on 0–10, and the mean, both counted on the people who answered on the scale. A “don’t know” code sits outside the scale and is left out of both.
Ask for the mean and the card leads with the mean. Ask for the NPS on a 0–10 question and the card leads with the NPS. A frequency scale (“once a week”, “every day”) has no favourable end and stays a plain count.
Name the box yourself, “top 3 box”, “bottom box”, “T2B”, and the card counts that box in place of the default. The receipt names the codes in the box, so the figure cannot be mistaken for the default one.
Nets
“Aware of any of these brands” on a tick grid is the share of people who ticked at least one of the columns, counted person by person on the rows, because the per-column counts cannot tell whether one person ticked two. “None of them” is the rest. Name some of the items and the net runs over those only; the card lists them. “Flanders or Brussels” on a single question is two answers of that question added up.
Every net names its columns or its codes on the card and in the receipt. A grid net needs the rows, so it runs on the desk. The client page says so instead of guessing from the counts.
Amounts and bands
A weekly spend, an age, a number of children: the figure an amount leads with is the mean, on the people who gave a number. Codes that stand for “no answer” are left out by name. The desk takes them from the file where it says so (SPSS user-missing, a label like “Refused”), and otherwise recognises the two conventions every research team uses: all nines above every real value, and a negative code on an amount that is otherwise never negative. The card says which codes were excluded.
Ask for a band and the figure is the share whose number falls in it: “over €50”, “under 25”, “between 30 and 50”, “3 or more”. The base is the same people who gave a number, with the same codes left out. “Over 50” leaves 50 out, “50 or more” takes it in, and “between” takes both ends in. A weight in the file applies to the share. The band is named on the card and in the receipt with its count and its base, so anyone with the file can count it again.
Rankings
A file carries a ranking question one of two ways: one column per item holding the place it was given, or one column per place holding the item put there. The desk reads both from the rows when a study is added, and is strict about it. A group of columns is a ranking only when the people who answered gave different values to different columns nearly every time, which a scale grid or a tick grid never does. Both kinds read as one table.
For every item: the share who put it first, the share who placed it in the top N, and its mean rank among the people who placed it, with 1 the best. Shares are on the people who ranked anything. A weight in the file applies to the shares; the counts beside them stay unweighted people, and the mean rank is unweighted. Ask “top 3”, “first choice” or “mean rank” and the card leads with that reading. When the question does not say, N is 3 on four or more places and one less than the number of places on fewer. Add “by region” and the headline reading for the item you asked about is cut like any other share.
The receipt carries the kind of grid, the number of places, the reading, and for every item its first, top-N and placed counts and its mean rank.
Key drivers
“What drives overall satisfaction?” is the one piece of arithmetic on the desk that is more than a count, so here it is in full. The outcome is the scale or amount the question names. The drivers are the rated items of the largest grid of scales in the study, six attributes of “Satisfaction with Harborline on”, say, or, when there is no such grid, every other scale in the file. The card says which.
For each driver the desk takes the people who answered both it and the outcome on their scales, reads both scales so that a higher code is the more favourable end, and computes the Pearson correlation. Share of importance is that item’s r² over the sum of r² across the items listed, scaled to 100. A tick marks a correlation different from zero at the 95% level on that item’s pairs. An item with fewer than 30 pairs is listed as left out and is not estimated. The correlations are unweighted, even on a weighted wave; the top-box column beside them is weighted like the rest of the card, and the card says so. With fewer than two items over the floor there is no table, and the card gives the reason.
That is all it is. There is no regression, so the shares do not allow for items that move together: two attributes that people rate alike will share the credit between them. There are no relative weights or Shapley values, and no judgement about which items to drop. The point is that a second person with the same file lands on the same table. The receipt carries the specification: the outcome field, the method, the pairs floor, and every row’s pairs, r and share.
Segmentation and conjoint stay in your stats package, and so does a regression. Write the result back into the file as a column and the desk cuts by it like any other question. A driver table needs the rows, so it runs on the desk, and the client page says so.
Who was asked
A questionnaire asks some questions only of some people. The response file does not carry that logic, so most tools show “of 459” and leave the reader to look up why. The desk reads the routing back from the pattern of blanks: for each question with blanks, it looks for the question whose answers explain them. When the rule fits, the card says so in a sentence: “Asked only of the 484 who ticked the brand on the awareness question.” When the fit is good but not exact, it says “mainly” rather than “only”. When no rule fits, nothing is claimed.
The reading band
A figure rests on choices a reader never sees: whether the don’t-knows sit in the base, and which of two look-alike questions was meant. A chat picks silently. A crosstab tool makes you pick. The desk counts the figure the one way the question asked for, then counts it again each other reasonable way, and says whether it held.
“With don’t-knows in the base it is 35.4%. The figure holds.” is a number that can be used as it stands. “Careful: if you meant the unaided question it is 27.8%, against 13.5% as counted.” is a number whose wording should be read out before it is used. Only a look-alike the study itself names counts as another reading. The receipt stays on the one reading the question asked for.
Waves
Each wave is its own file. A question is counted on each wave where it has a column, and nowhere else. With two waves the card marks the move between them: “+4.2 points from Last season to Next season. A real change, at the 95% level, on 100 and 100 people.” or “Within what chance would give.” The test is a two-proportion z for shares and a Welch z for means, on effective bases when both waves carry a weight.
Under the cards sits a table across the waves: each wave’s figure, its base and effective base, the change against the wave before, and whether that change is real at the 95% level. Each wave is tested against the one before it, on effective bases when both carry a weight and on unweighted bases otherwise; the footnote says which. A wave where the question was not asked is a blank row, and nothing is tested across it. With three or more waves the card draws the line as well.
“CSV, every wave” writes the cards out as one file: a block per wave, each ending in its own receipt hash and the address to verify it, and the table across waves at the bottom with the hash of each wave’s card on its row.
The mark between waves and the table across them are reading aids. Neither is part of any receipt. Each wave’s card has its own.
The receipt
Every result, counted or refused, gets a receipt: a SHA-256 hash
over the study, the wave, the question as typed, the field it
bound to, the base, every answer row with its count and
percentage, a fingerprint of the codebook, and
model=none. Where a cut, a narrowing, a weight, a
scale or an amount was involved, that is in the hash too. So is
the specification of anything counted beyond a share: the box as
you named it, the columns or codes of a net, the band with its
bounds, the ranking’s places and every item’s counts, and the
driver method with its pairs floor and every row’s pairs, r and
share.
Run the same question on the same file a year later and the
hash matches. Change one row and it does not. Anyone with the
receipt can re-hash it at /verify on the desk,
without a login. The response file is never part of the
receipt and never leaves your login.
Ask across every study on your desk and each study keeps its own receipt. There is no blended hash because there is no blended figure.
See the rules at work.
The Harborline sample on the homepage runs this exact engine, on our server in Frankfurt. Ask it for a cut, a narrowing, a mean. Your own file goes on the desk, behind your sign-in.